The Konklab and the Alvarez Lab together make up the
Harvard Vision Sciences Lab.
We run a joint operation, with a combined lab group doing collaborative science together in an integrated lab space.
To see our current people, research, publications, resources, and how to join, head over to:
visionlab.harvard.edu →
Harvard Vision Sciences Lab.
We run a joint operation, with a combined lab group doing collaborative science together in an integrated lab space.
To see our current people, research, publications, resources, and how to join, head over to:
visionlab.harvard.edu →
About me

Talia Konkle
talia_konkle@harvard.edu William James Hall 780
33 Kirkland St
Cambridge, MA
talia_konkle@harvard.edu William James Hall 780
33 Kirkland St
Cambridge, MA
I'm a vision scientist working at the intersection of cognitive neuroscience and AI.
At Harvard University, I'm a Professor of Psychology and Director of the Mind Brain Behavior Interfaculty Initiative,
as well as a member of the Center for Brain Science and the Kempner Institute for the Study of Natural and
Artificial Intelligence.
My research aims to understand how we see and make sense of the visual world. How are patterns of light transformed into meaningful representations of what we infer to be out there—objects, agents, and the environments they inhabit?
My work takes a NeuroAI approach, treating deep neural networks as model organisms. We build biologically inspired motifs into these models at an intermediate scale of organization, exploring how different mechanisms, architectural priors, visual diets, and learning goals give rise to different artificial visual systems. We study how these systems work and how well they capture patterns in human brain activity and behavior, using these comparisons to gain insight into biological vision.
To ground this work, we use functional neuroimaging to map how visual responses are organized across the human cortical surface, we collaborate with neurophysiologists to probe finer-grained neural response properties, and we draw on the rich experimental traditions of visual cognition to characterize human perceptual and cognitive capacities.
Broadly, I am inspired by considering the experience and needs of an active observer in the world—this thinking continually deepens my understanding of how behavioral capacities are expectant in the local and long-range architecture of the brain, and how neural networks absorb the statistics of visual experience to realize the functions latent in the structure.
Selected recent publications
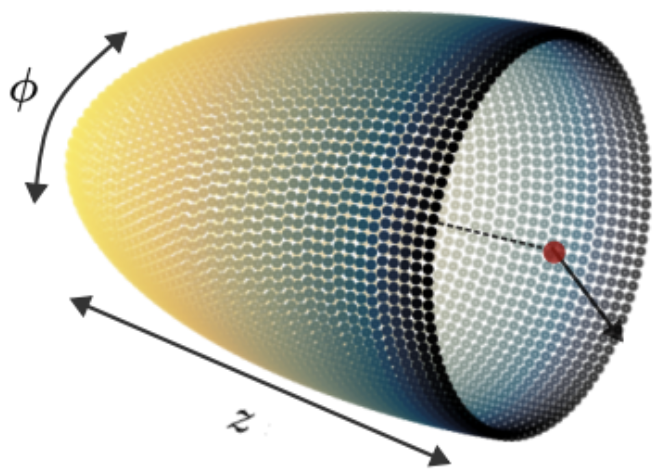 FOVI: A biologically-inspired foveated interface for deep vision models
Blauch, Alvarez, & Konkle (2026). International Conference on Machine Learning
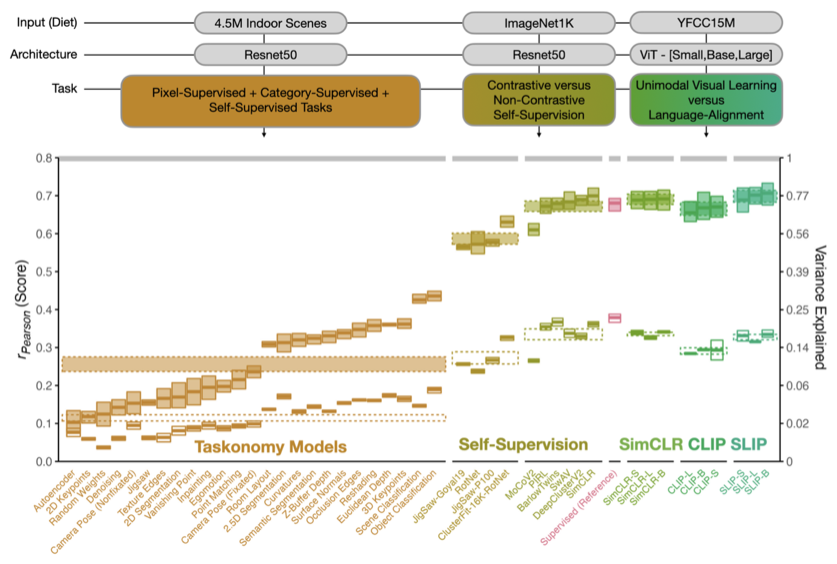 A large-scale examination of inductive biases shaping high-level visual representation in brains and machines
Conwell et al. (2024). Nature Communications
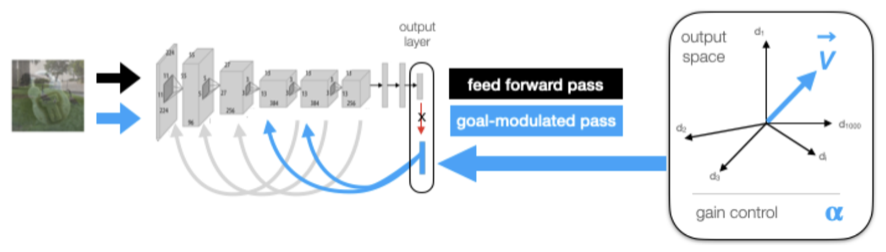 Cognitive steering in deep neural networks via long-range modulatory feedback connections
Konkle & Alvarez (2023). NeurIPS
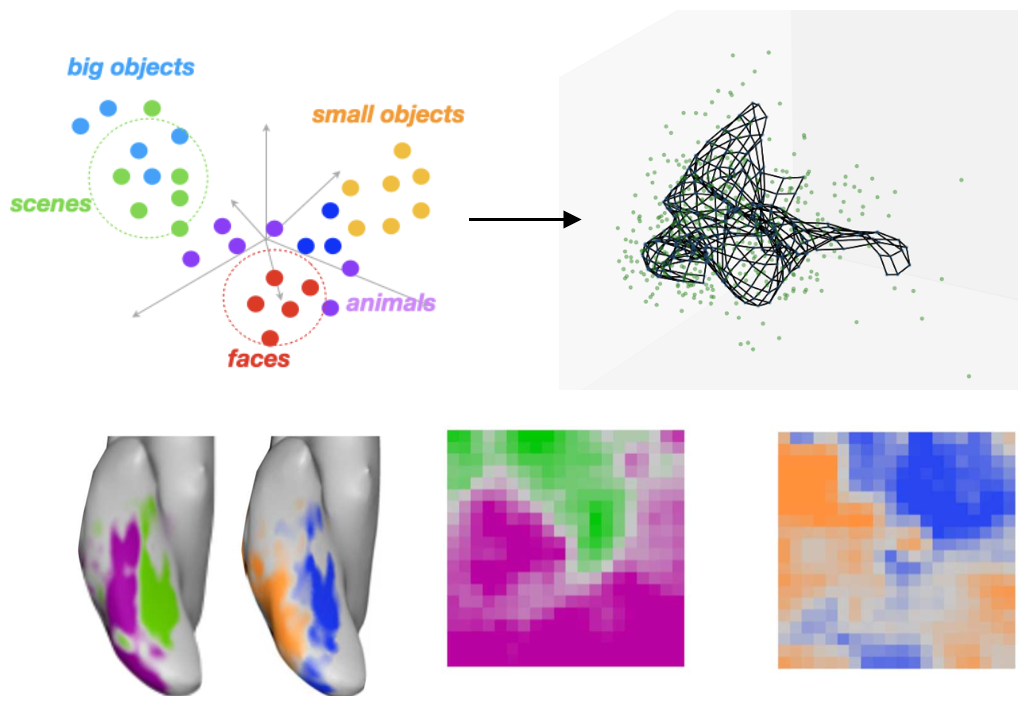 Cortical topographic motifs emerge in a self-organized map of object space
Doshi & Konkle (2023). Science Advances
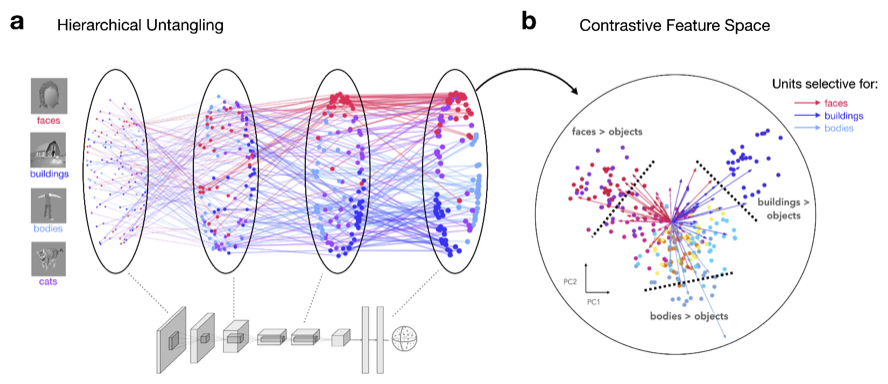 Contrastive learning explains the emergence and function of visual category-selective regions
Prince, Alvarez, & Konkle (2024). Science Advances
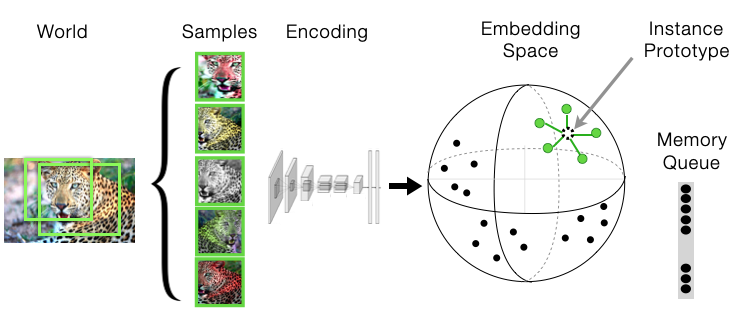 A self-supervised domain-general learning framework for human ventral stream representation
Konkle & Alvarez (2022). Nature Communications
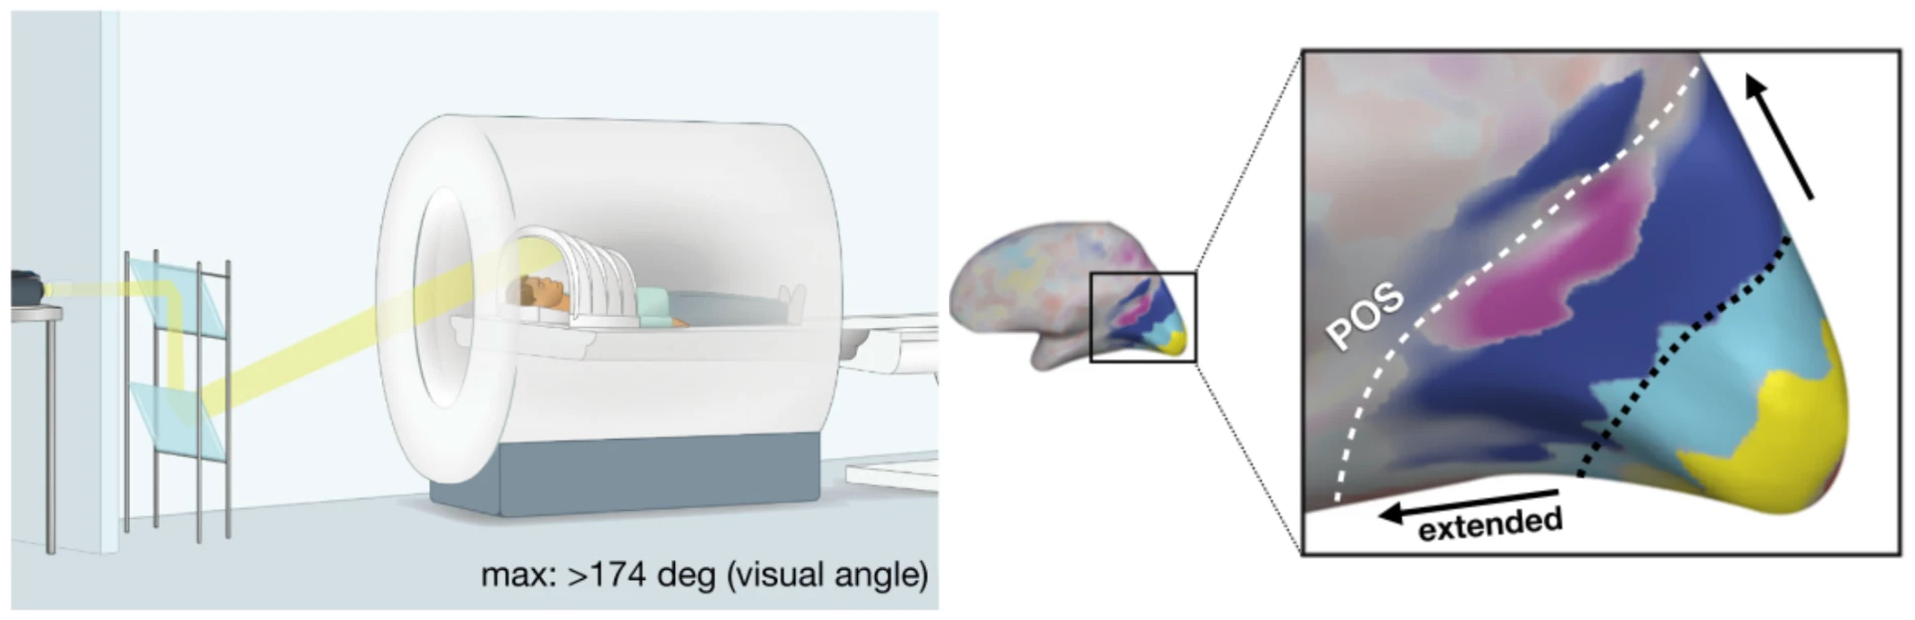 Immersive scene representation in human visual cortex with ultra-wide-angle neuroimaging
Park et al. (2024). Nature Communications
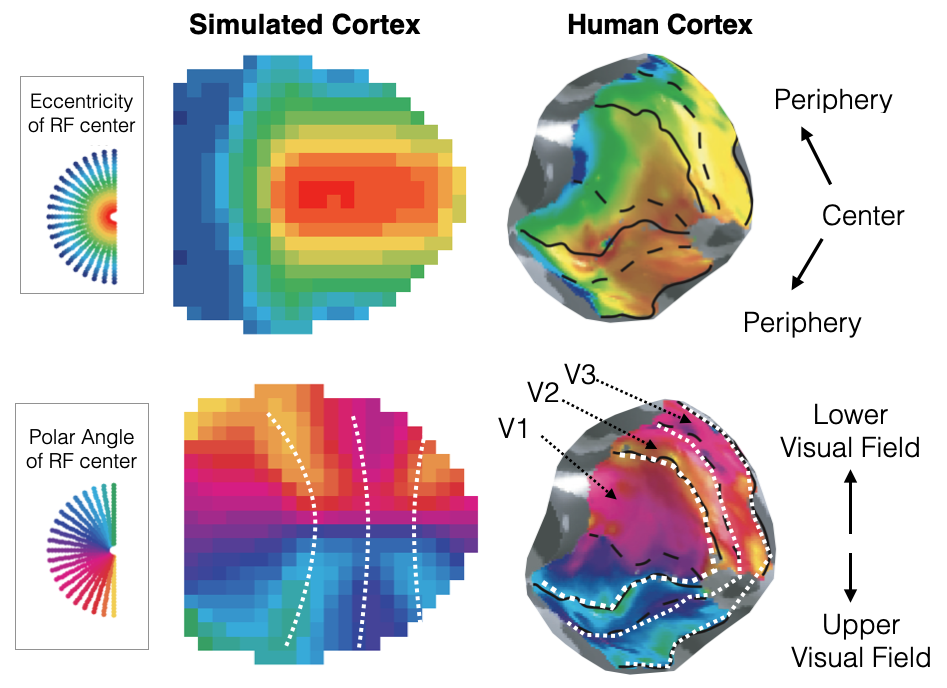 Emergent organization of multiple visuotopic maps without a feature hierarchy
Konkle (2021). bioRxiv
Some Talks
 A High-Fidelity Perceptual Interface of the Visual World
Cognitive Science Society, Lila R. Gleitman Award, 2023
 Why is that there? Feature mapping across the visual cortex
Cognitive Computational Neuroscience keynote, 2019
Earlier research

Animacy and real-world size organize object cortex
Object responses across occipitotemporal cortex are organized by real-world size and animacy,
and this large-scale organization is mirrored in resting-state network architecture.
- A real-world size organization of object responses in occipito-temporal cortex. Konkle & Oliva (2012). Neuron
- Tripartite organization of the ventral stream by animacy and object size. Konkle & Caramazza (2013). Journal of Neuroscience
- The large-scale organization of object-responsive cortex is reflected in resting-state network architecture. Konkle & Caramazza (2016). Cerebral Cortex

Visual features carry categorical structure
“Texforms” preserve texture and rough shape while making objects unrecognizable.
These features alone are sufficient to evoke the brain’s broad organization by animacy and real-world size,
revealing how visual appearance carries information about these categories.
- Mid-level visual features underlie the high-level categorical organization of the ventral stream. Long, Yu, & Konkle (2018). PNAS
- Mid-level feature differences underlie early animacy and object size distinctions: Evidence from EEG decoding. Wang, Janini, & Konkle (2022). Journal of Cognitive Neuroscience

Mapping the reachable world
Between close-up views of objects and far-scale scenes lies the reachable world—the countertops,
desks, and workbenches where we use our hands. Images of these “reachspaces” evoke a distinct large-scale
topography in visual cortex, and are perceptually distinct from both objects and scenes. To support this work, we built the
Reachspace Database, with over 10,000 images.
- Large-scale dissociations between views of objects, scenes, and reachable-scale environments in visual cortex. Josephs & Konkle (2020). PNAS
- The world within reach: an image database of reach-relevant environments. Josephs, Zhao, & Konkle (2021). Journal of Vision
- Dimensions underlying human understanding of the reachable world. Josephs, Hebart, & Konkle (2023). Cognition

Seeing actions
Visual responses to actions are organized into large-scale networks—one reflecting the social
aspects of an action, and others reflecting the scale of its “interaction envelope,” from fine manipulations
of objects to whole-body movements through space. People intuitively group actions by goals, but visual brain
responses more closely reflect body configuration—the visual system captures the precursors to action understanding.
- Sociality and interaction envelope organize visual action representations. Tarhan & Konkle (2020). Nature Communications
- Behavioral and neural representations en route to intuitive action understanding. Tarhan, De Freitas, & Konkle (2021). Neuropsychologia

Texforms: seeing what things are without knowing what they are
Texforms are synthesized images that preserve an object's local texture and coarse form,
but can't be recognized. Even so, people can tell whether a texform depicts something big or small,
animate or inanimate—and real-world size is processed automatically, without recognition.
Read more in the texform FAQ,
or generate them with the original
or accelerated code.
- Mid-level perceptual features distinguish objects of different real-world sizes. Long, Konkle, Cohen, & Alvarez (2016). JEP:General
- A familiar-size Stroop effect in the absence of basic-level recognition. Long & Konkle (2017). Cognition
- Animacy and object size are reflected in perceptual similarity computations by the preschool years. Long, Moher, Carey, & Konkle (2019). Visual Cognition

Linking neural organization and perception
Different object categories compete to different degrees in perception and memory—and that
competition is predicted by the similarity of their responses across object-responsive cortex, pointing to a common
representational bottleneck.
- Processing multiple visual objects is limited by overlap in neural channels. Cohen, Konkle, Rhee, Nakayama, & Alvarez (2014). PNAS
- Visual awareness is constrained by the representational architecture of the visual system. Cohen, Konkle, Nakayama, & Alvarez (2015). Journal of Cognitive Neuroscience
- Visual search for object categories is predicted by the representational architecture of high-level visual cortex. Cohen, Alvarez, Nakayama, & Konkle (2017). Journal of Neurophysiology

Real-world size shapes how we represent objects
Objects occupy a physical, three-dimensional world, and their size constrains how we see and
interact with them. This structure is reflected in our minds: objects have a preferred visual size when drawn, imagined,
or viewed, which scales with their real-world size. This size knowledge is also activated automatically when we
recognize an object, already by the preschool years.
- Canonical visual size for real-world objects. Konkle & Oliva (2011). JEP:HPP
- A familiar size Stroop effect: Real-world size is an automatic property of object representation. Konkle & Oliva (2012). JEP:HPP
- Real-world size is automatically encoded in preschoolers’ object representations. Long, Moher, Carey, & Konkle (2019). JEP:HPP

How much can we remember about what we see?
After seeing thousands of objects, people can remember not just which ones they saw,
but fine details of their appearance. What makes this extraordinary capacity possible? Surprisingly, what matters is
not simply how different the objects look, but how conceptually distinct they are. Our work points to how knowledge
organizes memory: conceptually distinct objects interfere less with one another, helping preserve visual detail.
- Visual long-term memory has a massive storage capacity for object details. Brady, Konkle, Alvarez, & Oliva (2008). PNAS
- Conceptual distinctiveness supports detailed visual long-term memory. Konkle, Brady, Alvarez, & Oliva (2010). JEP:General
- A review of visual memory capacity: Beyond individual items and toward structured representations. Brady, Konkle, & Alvarez (2011). Journal of Vision
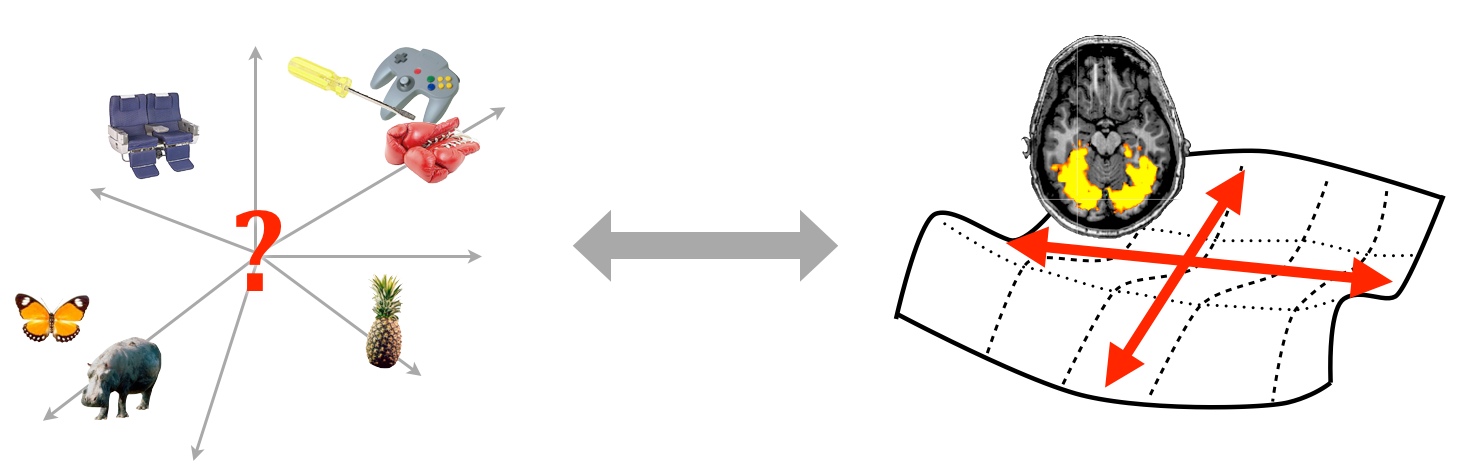
Original Konklab logo (2015)
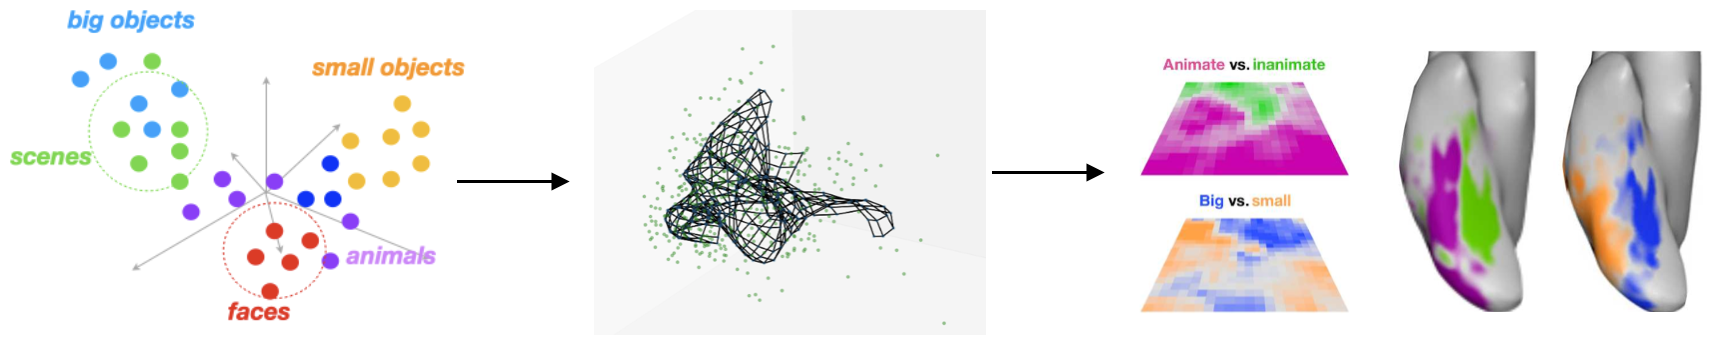
Smooth mapping of a deep-neural network feature space, Doshi & Konkle (2023)